When an enterprise agent reads a report, API response or spreadsheet, where does the information live on its next reasoning turn? Often, it remains in conversation history. Every follow-up then carries that payload forward, even when the model no longer needs it. The result: recurring token cost, crowded context and a higher chance that useful details disappear in stale output.
AI agent filesystem memory offers a complementary approach: keep operational artifacts in a governed workspace and give the model compact references plus targeted read operations. It does not replace a vector database; it gives agents a place for exact files, intermediate results and workflow state that should not be repeatedly restated in natural-language context.
The hidden cost of treating conversation history as storage
A conversation is a useful interface for reasoning, but a poor general-purpose data store. A 300-row tool response may be relevant for one calculation and irrelevant for the next ten steps. If the orchestration layer keeps appending it verbatim, the agent repeatedly pays to resend data it could query selectively. Tool results also compete with the user’s goal, policies and recent decisions for attention. More context is not the same as more useful context.
| Conversation-as-storage | Workspace-backed memory |
|---|---|
| Full tool output travels through later turns | Raw output remains in a file; turns carry a path and summary |
| Selection depends on scanning a long transcript | Targeted search and line-range reads retrieve needed evidence |
| Intermediate artifacts are hard to audit | Files can be named, inspected, compared and retained |
| Context grows with every operation | Context focuses on decisions and relevant excerpts |
Vector retrieval and filesystem memory solve different problems
Vector databases find semantically relevant passages across a corpus. They are useful when a question is phrased differently from a policy or document. A workspace disk serves another job: storing concrete artifacts consumed or produced during a task—an uploaded workbook, parsed API result, intermediate JSON or report under construction. Such artifacts need stable identity and exact access; they may not need chunking, embeddings and semantic ranking.
| Need | Best fit | Example |
|---|---|---|
| Find the policy passage that answers a question | Vector or hybrid retrieval | Search a handbook corpus |
| Read a specific response exactly | Workspace filesystem | Inspect saved connector JSON |
| Continue a multi-step transformation | Workspace filesystem | Normalize rows, then generate a report |
| Find an exact ID or error string | Lexical file search | Locate a customer key |
A robust Enterprise AI Harness often needs both: knowledge retrieval for “what does our policy say?” and file-backed memory for “what did this workflow retrieve, calculate and change?”
How Koios keeps large payloads out of the active prompt
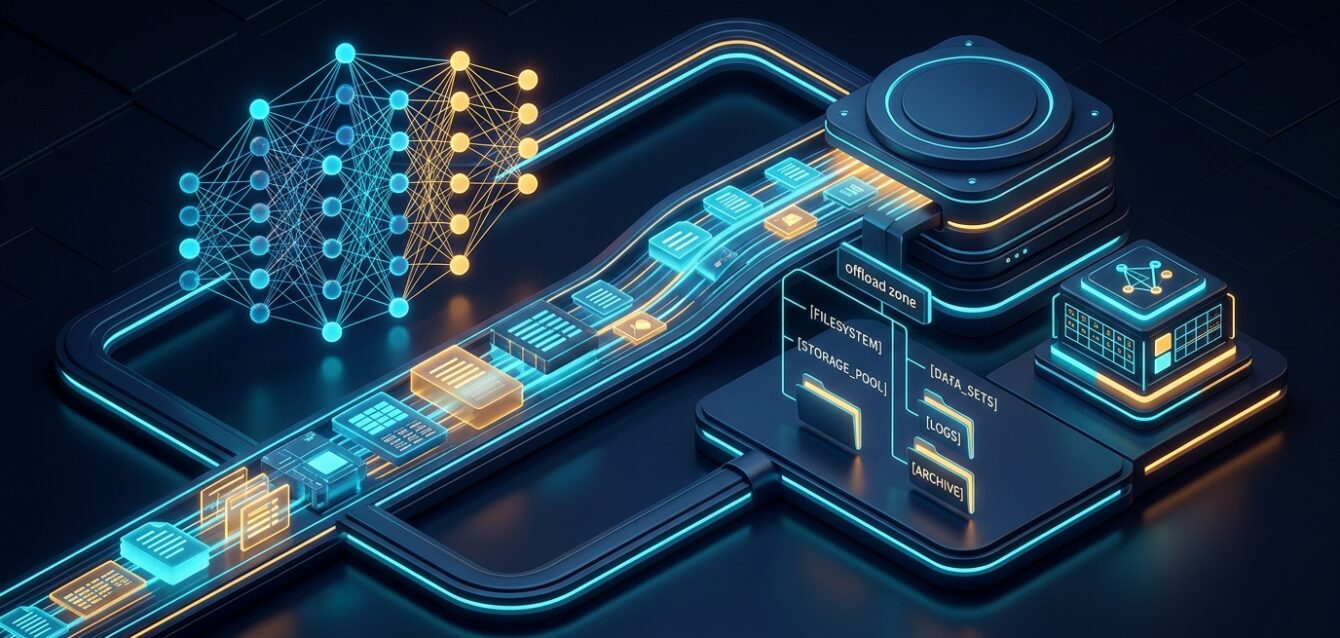
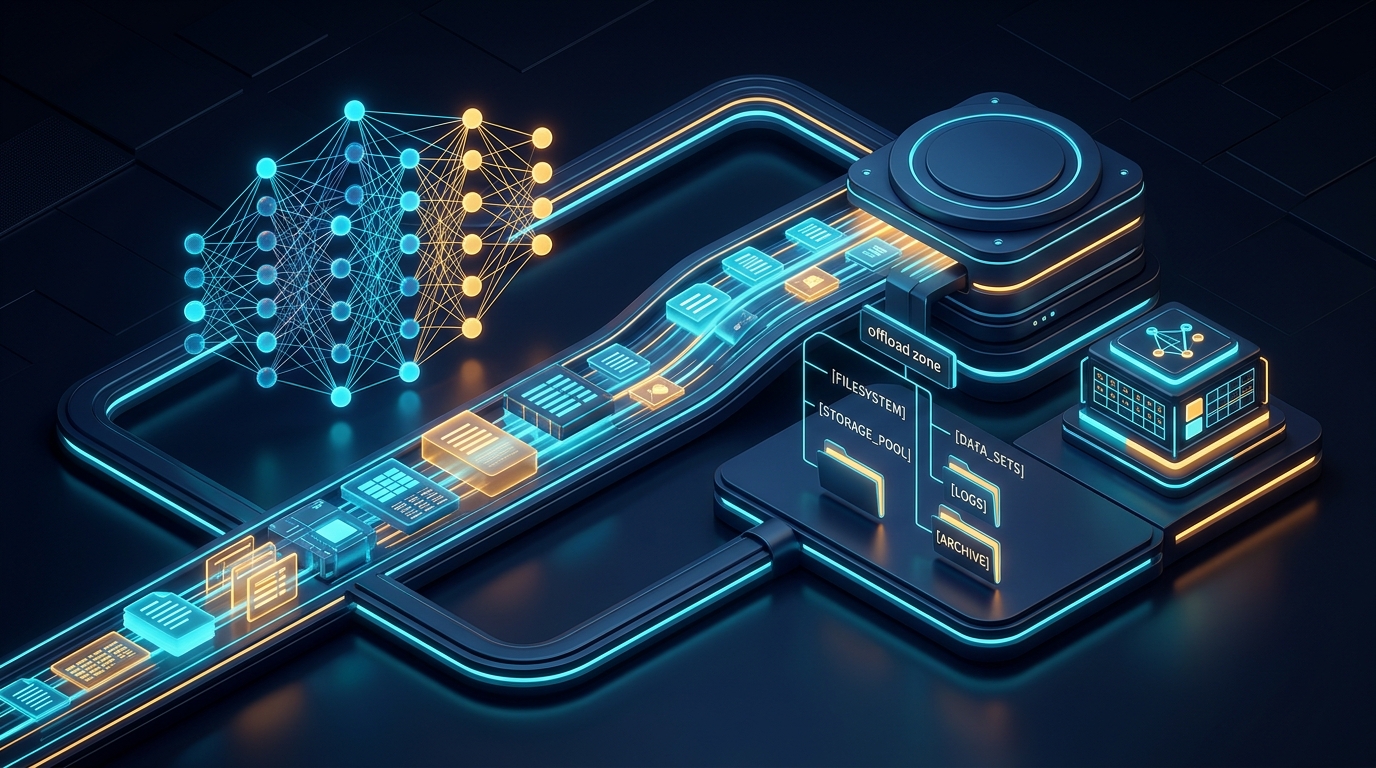
Koios gives agents workspace operations such as ls, cat, grep, write and patch. When a tool response exceeds 2 KB, the runtime can spill the full result to a /scratch/ file and return a compact envelope with the path, size and summary. The agent can inspect only relevant lines or search for a value instead of carrying the entire payload forward.
{
  "status": "success",
  "spilled_to_disk": true,
  "path": "/scratch/tool_output_abc123.json",
  "size_bytes": 14820,
  "summary": "Retrieved records; use grep or cat with line ranges to inspect."
}
The principle is simple: preserve the source artifact, return a pointer, and request only the slice the next operation needs. A grep for a record ID, paginated read or narrow line range reduces the working set. Intermediate state becomes an explicit workspace object rather than an invisible lump in the transcript.
A practical workflow: retrieve, spill, query, synthesize
- Retrieve: call the connector or read the source document.
- Spill: retain large output in a scoped workspace path; return a compact reference.
- Query: use exact search, structured parsing or paginated reads.
- Transform: write normalized data to a new artifact instead of silently overwriting the source.
- Synthesize: include relevant facts, citations and caveats in the final response.
- Clean up: apply retention and access controls to scratch data according to sensitivity.
Tool response > 2 KB
  ├─ full payload → /scratch/result.json
  └─ compact pointer → model context → grep / paginated read → derived artifact
For example, an agent summarizing support cases can save the full response, search for an account, inspect matching records and produce a report pointing back to its source. This keeps the reasoning context smaller without pretending the summary replaces the evidence.
Designing workspace memory safely
Disk offloading is not automatically secure because data sits outside a prompt. Treat the workspace as a governed data plane: define read/write permissions for nodes, separate tenant and workflow scopes, apply retention to temporary material and avoid logging secrets in summaries. Keep source artifacts immutable where possible and write transformations to separate paths. For regulated use, capture enough provenance to trace operations performed.
Distinguish working data from durable knowledge. Scratch outputs may be disposable; approved company documents belong in a managed knowledge base. Avoid embedding every intermediate result just to make it searchable, and do not retain sensitive temporary files indefinitely. Expiration and cleanup are part of the architecture.
What to measure before claiming token savings
Benchmark representative tasks before and after filesystem offloading. Record input tokens per reasoning turn, total tokens per completed task, latency, repeated payload bytes, retrieval accuracy and task failure rate. Compare equivalent workflows and include parsing, storage and tool-call costs. The goal is not simply for the model to see less data; it is for it to see the right evidence while maintaining correctness.
Ask how often stored artifacts are reread, how much response data travels into subsequent turns, whether a reviewer can reproduce the answer from retained files and whether scratch files are removed on schedule. A system that reduces prompts but cannot explain its conclusions has traded cost for auditability.
Filesystem memory is one layer of the AI harness
Vector search remains the right tool for semantic discovery across organizational knowledge. A governed workspace disk complements it for exact, task-specific operational state. Combined with Just-In-Time tool discovery, surgical diff patching and scoped execution, the Enterprise AI Harness lets agents work without turning every intermediate response into permanent conversational baggage.
Keep durable knowledge searchable, workflow artifacts addressable and prompts focused on decisions. For teams scaling agents, filesystem memory is not a replacement for context engineering; it is operational infrastructure that makes context deliberate.
Related reading: Just-In-Time Tool Discovery and Surgical Diff Patching. For retrieval background, see pgvector documentation.